Shipping Price Decisions on Azure ML: Jobs, Storage Handoffs, and Gaps I’d Fix First
Parts 1–3 built the commercial loop: demand curve, 5¢ grid, dual change gate. This post is the shipping layer — how those jobs actually run on Azure without a leftover disk and a hope.
One sentence: an azure machine learning pipeline here is a parent job whose child steps pass versioned folders, score store×SKU slices in parallel, then upsert a gated decision — not a notebook that “ran on the cluster once.”
Examples use Harbourline Mart — a fictional multi-store grocer I made up for this series, not a real company. Engineers get the job graph and storage contract. Managers get one scoreboard: can we re-run Tuesday and still see one row per store×SKU×day?
Read first if you skipped them: Shelf Price Decision Systems, Multi-Store Demand Models, and Scoring a Shelf-Price Grid. Same framing as the AI architecture and security-review posts: boundaries beat hero models.
What an azure machine learning pipeline owns here
Analogy: a pizza chain. Head office owns the recipe card (the registered model bundle). Each store oven is a worker that bakes one night’s tickets (a mini-batch of store×SKU slices). The walk-in fridge is Blob / ADLS — if the next shift cannot find the dough by a named shelf, you do not “use last night’s tray on the counter.” That tray is node-local disk. It dies with the VM.
That is the mlops azure conversation I have with category leads: cadence and contracts, not a new booster every sprint. When people say enterprise ai architecture for pricing, I mean this shape — classical ML plus explicit publish rules — not a chat model inventing stickers.
What this layer owns:
- A parent pipeline job (v2 DAG) with child command and parallel jobs
- Storage handoffs as
uri_folder/mltable/ data assets — not assumed paths - Schedules with a real
time_zone, not a comment in the README - A quality gate before register, and upsert before the UI
What it does not own: printing stickers, inventing COGS, or “the model decided $3.47.” Humans still own the board. Software owns the evidence pack. Microsoft’s v2 docs match the shape: a pipeline is a job whose children form a DAG; a parallel job is only valid as a step in that pipeline, not a lone hero run. SDK v1 pipelines are deprecated (31 Mar 2025) with support ending 30 Jun 2026 — I author v2 YAML.
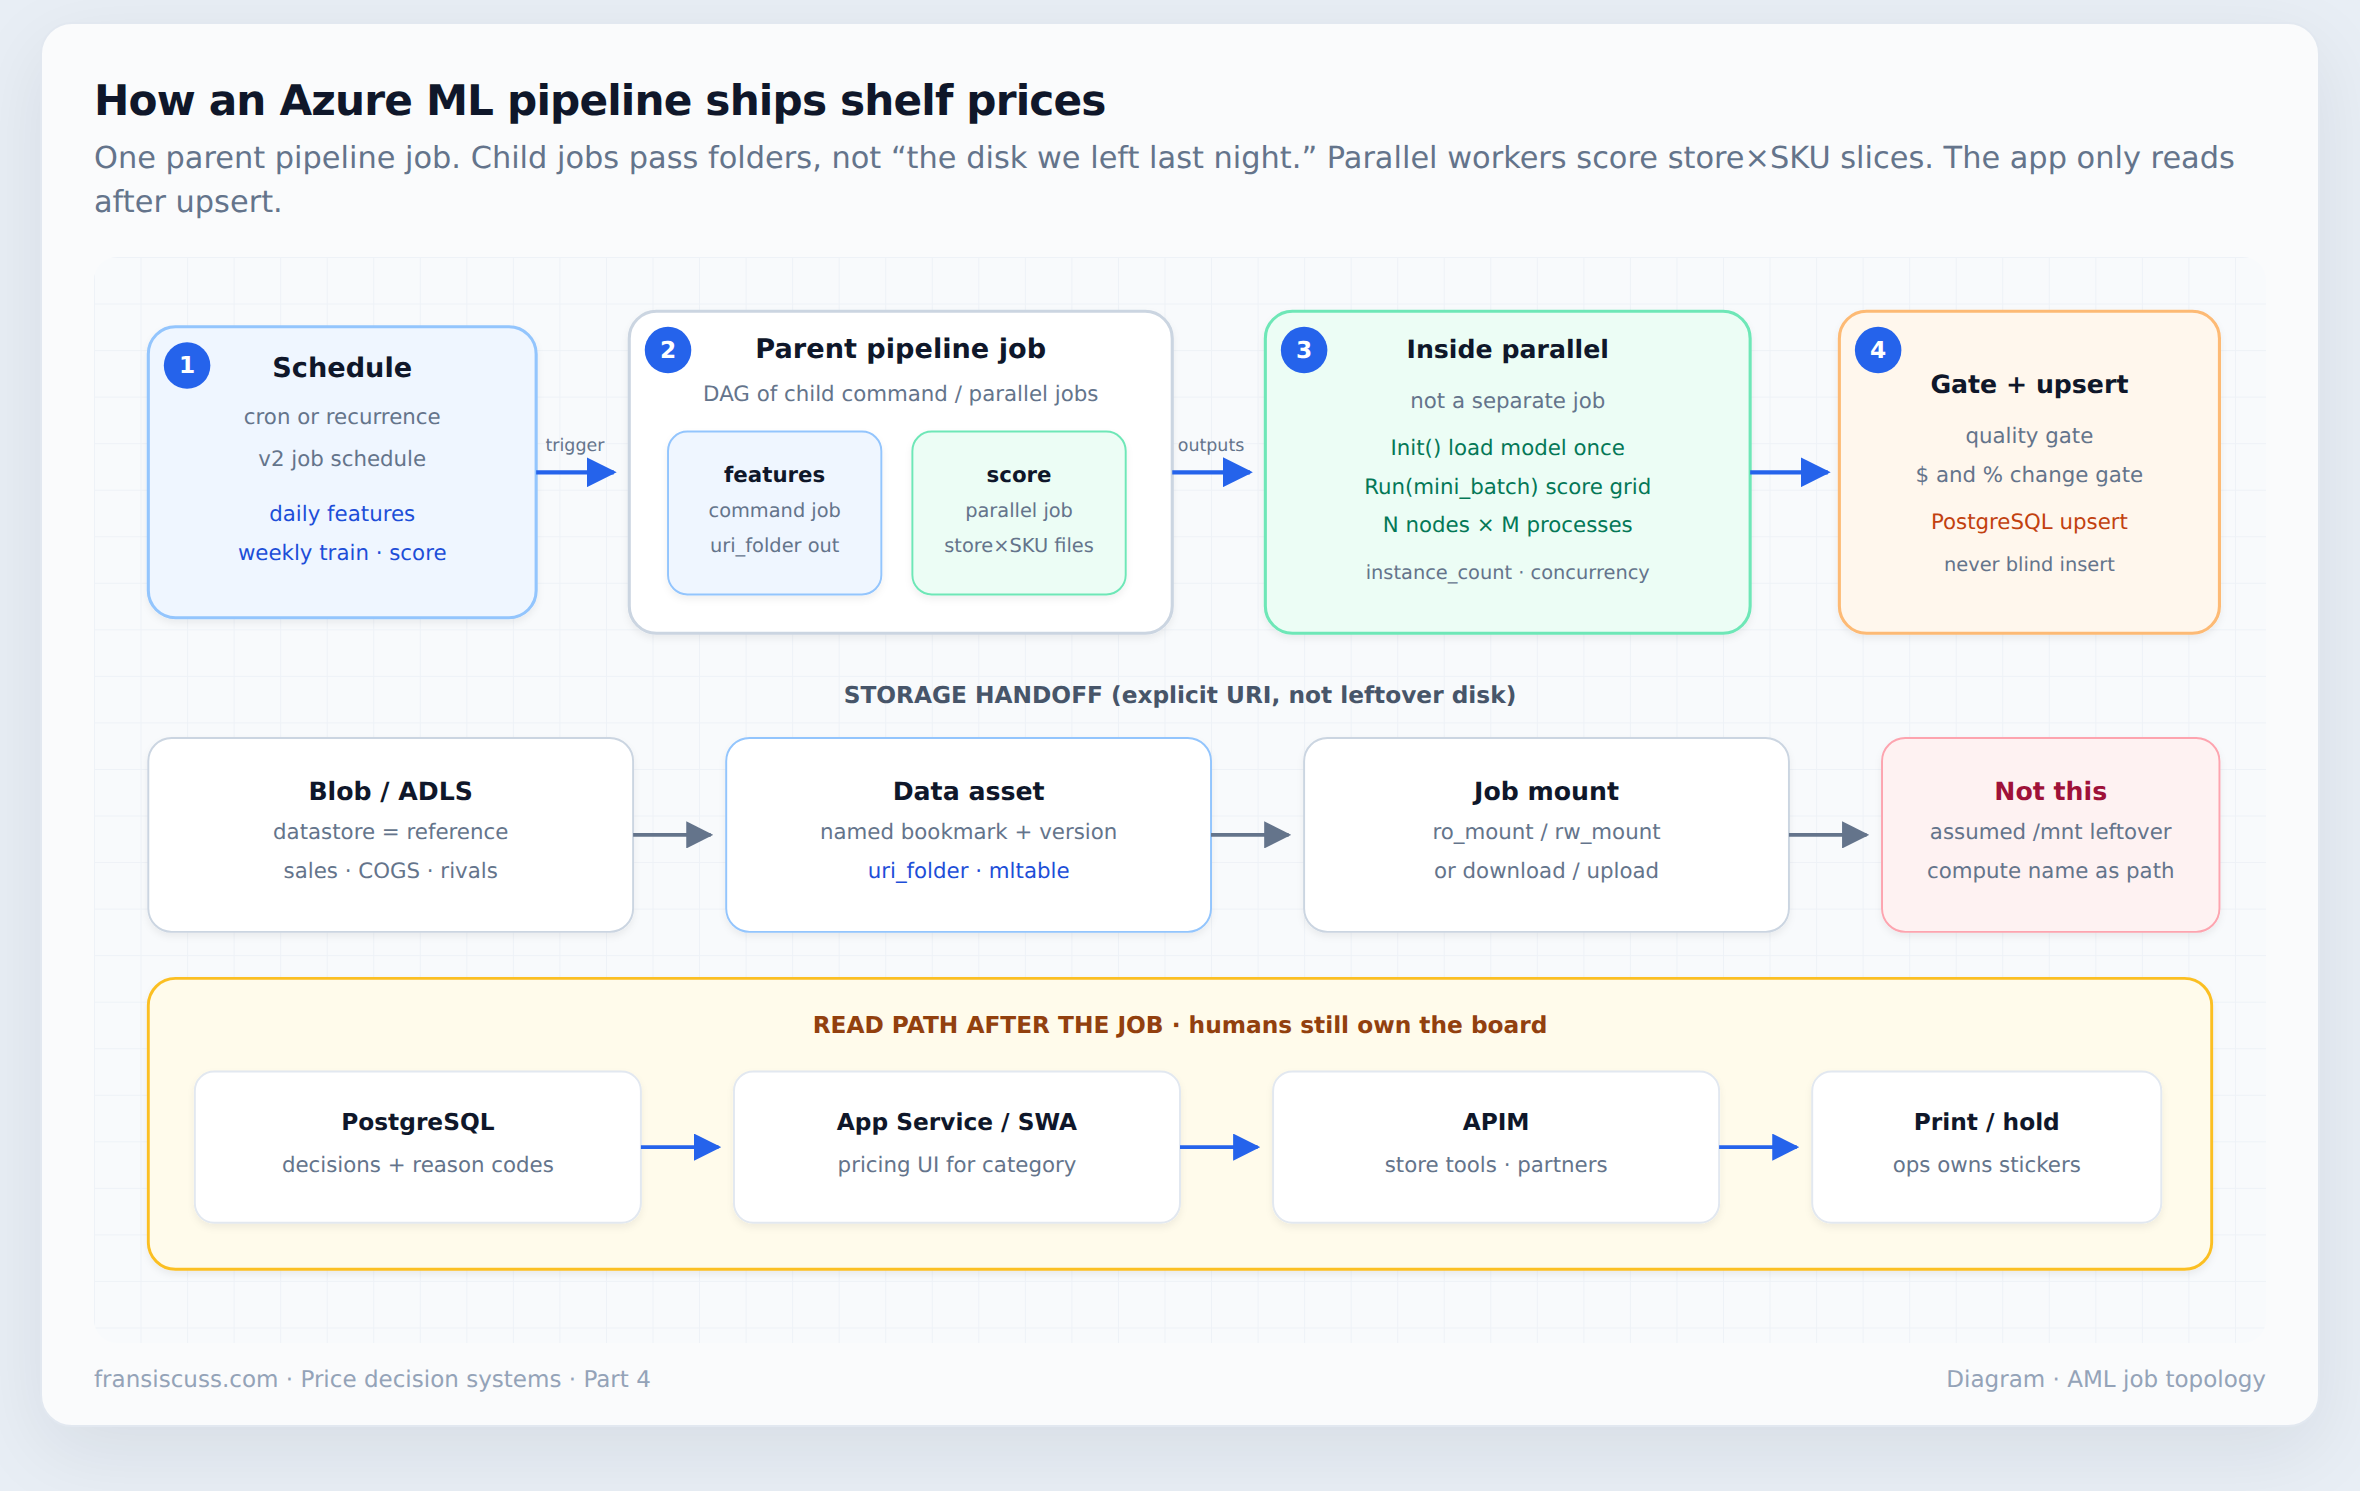
Orchestrator, parallel workers, process pool
I keep three runtimes in my head. Mixing them is how Harbourline’s fictional Tuesday job “succeeded” and still missed 40 stores.
| Piece | AML v2 name | What I use it for |
|---|---|---|
| Orchestrator | Parent type: pipeline job |
Order: features → score → gate → write. Sibling outputs use ${{parent.jobs.<step>.outputs.<name>}}; pipeline inputs use ${{parent.inputs.<name>}}. |
| Serial step | Child type: command |
One script, one node: daily feature build, register bundle, upsert. |
| Workers | Child type: parallel |
Split store×SKU files or an mltable. instance_count nodes × max_concurrency_per_instance processes. |
| Process pool | Entry script Init / Run(mini_batch) |
Load LightGBM once per process in Init. Score the grid inside Run. Return a list/frame so AML can count successes. |
Composite shape only — this is not a workspace dump:
# pipeline.score.yml — shape, not a real workspace
$schema: https://azuremlschemas.azureedge.net/latest/pipelineJob.schema.json
type: pipeline
display_name: harbourline-score-grid
settings:
  default_compute: azureml:cpu-cluster
jobs:
  features:
    type: command
    component: azureml:pds_features@latest
    outputs:
      feature_folder:
        type: uri_folder
  score:
    type: parallel
    inputs:
      input_data: ${{parent.jobs.features.outputs.feature_folder}}
      score_model:
        type: uri_folder
        path: azureml:harbourline_lgbm_bundle@latest
    input_data: ${{inputs.input_data}}
    mini_batch_size: "64"
    resources:
      instance_count: 4
    max_concurrency_per_instance: 8
    task:
      type: run_function
      code: ./score
      entry_script: score_grid.py
      environment: azureml:pds-score-env@latest
    outputs:
      scored:
        type: uri_folder
  gate:
    type: command
    component: azureml:pds_quality_gate@latest
    inputs:
      scored: ${{parent.jobs.score.outputs.scored}}
    outputs:
      passed:
        type: uri_folder
  publish:
    type: command
    component: azureml:pds_upsert@latest
    inputs:
      scored: ${{parent.jobs.gate.outputs.passed}}
Microsoft is explicit: the major parallel input is one splitable set — file list (uri_folder/mltable) or tabular mltable in direct mode. I pre-shard that folder one file per store×SKU slice and split by file count (mini_batch_size: "64"), not “whatever landed in cwd.” Tabular partition_keys is the other official path; I am not using it on this job. mini_batch_error_threshold is a fuse, not a way to ignore 30% of New South Wales.
Blob vs data asset vs assumed disk
Three objects people collapse into “the data.”
| Object | What it is | Smell if you skip it |
|---|---|---|
| Datastore | Workspace reference to Blob / ADLS (credential or identity). Default workspaceblobstore is fine for scratch, not for the commercial feature store. |
Account keys in scripts; every job talks to a different container. |
| URI types | uri_file, uri_folder, mltable. Modes: ro_mount / rw_mount / download / upload / direct. |
Hard-coded wasbs://… that only your laptop can see. |
| Data asset | Named, versioned bookmark over a URI. Cheap metadata, data stays put. | Jobs pin “whatever is in features/today/” with no version. |
| Node disk | Ephemeral. Useful for temp parquet inside Run. Not a handoff. |
“It worked on cpu-cluster-01.” Cluster scaled, path gone. |
I pass features as uri_folder outputs of the command step. Score writes another folder. Publish reads that folder and upserts. If a step needs a table with a shifting schema, that is mltable, not a tribal CSV layout in Slack.
Schedules that actually fire
v2 job schedules take a recurrence pattern or a cron expression. They do not take Event Grid. Microsoft documents that limitation; I do not pretend a blob-created trigger will start scoring.
Cron gotchas I have burned:
DAYSandMONTHSfields are ignored and treated as*.- Default timezone is UTC if you omit
time_zone. - A comment
# 4am AESTnext to0 18 * * *is not a contract. Puttime_zone: "AUS Eastern Standard Time"(or equivalent) on the schedule resource. - The author still needs job-submit permission even after you assign a managed identity to the schedule.
Cadence from part 1 still holds: daily features, weekly train, frequent score, gated publish. Three schedules, three pipeline YAMLs — not one mega-DAG that retrains LightGBM every hour “because compute is cheap.”
Read path after the job
AML is not the product. Category tools are.
- PostgreSQL holds the decision row: recommended price, runner-up, score delta, reason codes (hold / apply / freshness / calibration).
- App Service or Static Web Apps is the Monday UI.
- APIM fronts store-device and partner reads so a handheld does not talk to the workspace.
The UI must key on store×SKU×day. If you insert, a re-run creates twins and the handheld picks at random. That is not an ML bug. It is a primary-key bug with a model’s name on the ticket.
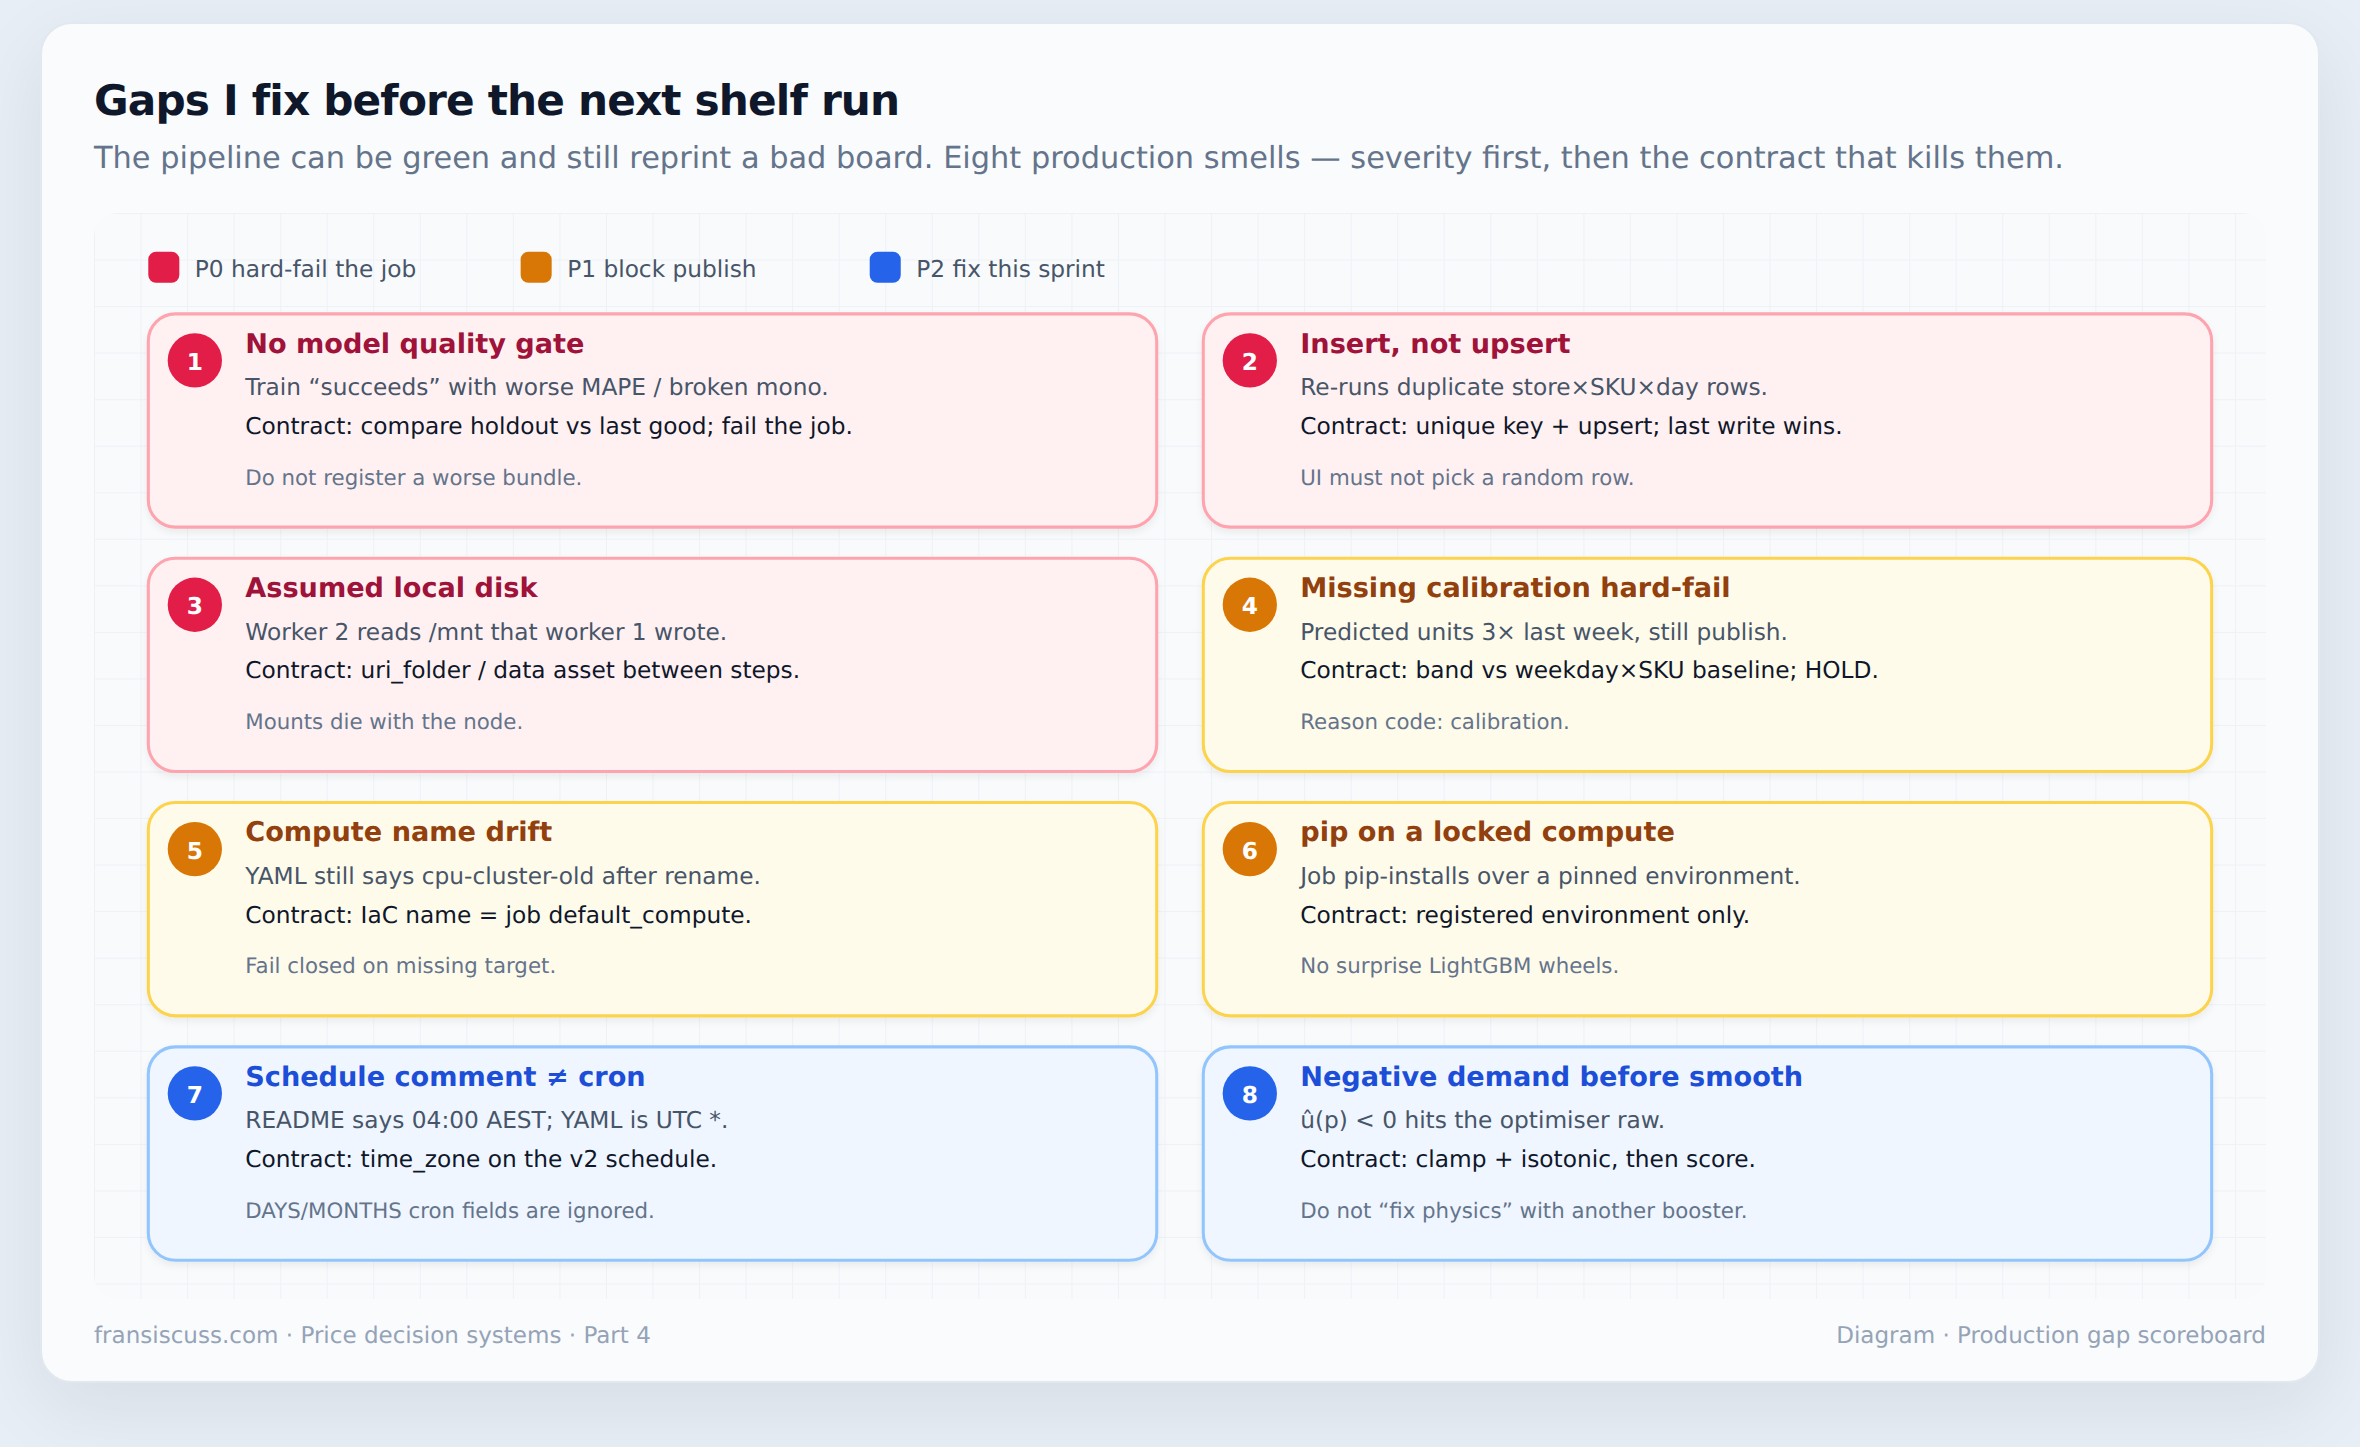
Model quality gates I actually fail the job on
Azure Machine Learning will happily mark a command job Succeeded if the process exited 0. That is not a model quality gate. I add a child step that compares the new bundle to the last registered one and to a weekday×SKU baseline. Fail closed — do not register, do not upsert “apply.”
| Gap | Why the board suffers | Fix I want in IaC |
|---|---|---|
| No quality gate | Worse MAPE or broken own-price monotonicity still registers. | Holdout vs last-good; exit non-zero; do not bump the data asset version. |
| Insert not upsert | Re-score duplicates the day. | Unique (store, sku, day) + ON CONFLICT DO UPDATE. |
| Assumed disk | Worker B cannot see worker A’s /mnt. | Only URI outputs between jobs. |
| No calibration hard-fail | û(p) is 3× last week; we still print. | Band vs weekday baseline → reason HOLD_CALIBRATION. |
| Compute name drift | YAML still names cpu-cluster-old. |
Terraform/Bicep name = default_compute. Missing target fails the schedule. |
| pip on locked compute | Job silently upgrades LightGBM. | Registered environment only. No pip install in the entry script. |
| Schedule comment ≠ cron | Features build after rivals land. Or before. | time_zone on the schedule; one dashboard of next-run times. |
| Negative demand before smooth | Contribution goes negative-weird; gate looks “random.” | Clamp ε then isotonic on the grid, as in part 3. Do not train a second booster “to fix physics.” |
Infra that is not in IaC is the quiet one. Cluster SKU, schedule, datastore identity, environment version — if it only exists in Studio clicks, the next engineer cannot rebuild Harbourline’s (fictional) Tuesday. I treat Studio as a debugger, YAML + IaC as the source.
Scoreboard for engineers and managers
| Question | Pass | Fail |
|---|---|---|
| Can we re-run today? | One row per store×SKU×day after upsert | Twins; UI coin-flip |
| Did the bundle earn the register? | Gate vs last-good + baseline | Exit 0 was enough |
| Where did features come from? | Versioned data asset | “On the cluster” |
| Who reprints the board? | Human + reason codes | Job writes the gun directly |
FAQ
Is this an azure machine learning pipeline or a bunch of command jobs?
A pipeline job is the parent DAG. Command and parallel jobs are children. If you only submit one command job, you do not get typed handoffs, a single Studio graph, or a schedule over the whole flow.
Do I need AML parallel jobs, or can workers be Azure Functions?
Functions are great at the integration edge. Scoring thousands of LightGBM slices is a parallel job (or Spark) problem: mini-batches, retries, Init once per process. I do not put the grid score on a 5-minute HTTP trigger.
What is a model quality gate if Studio already has metrics?
Logged metrics are a diary. Model quality gates here are child steps with an exit code, not a Studio product name. If MAPE, calibration band, or own-price monotonicity miss the contract, the job is Failed and the previous bundle stays @latest.
Why not event-based scoring when rival prices land?
v2 AML schedules are time-based only (recurrence or cron). Rival files can land in Blob on a different clock. I land features on a schedule after the expected rival drop, and freshness-fail in the optimiser if the file is stale — same dual-gate idea as part 3.
Is Harbourline Mart a real retailer?
No. Fictional name so the loop stays concrete without leaking any employer. Units are shelf SKUs, not anything else.
That is the four-part loop closed: decide, don’t predict → features and LightGBM slices → grid and gate → jobs you can re-run. Next Azure slot on this blog goes back to the integration connectors.
